ATOM™-Max Server
High Performing Server for Large-Scale AI Inference
Large-Scale AI Inference
Starts with a Single Server
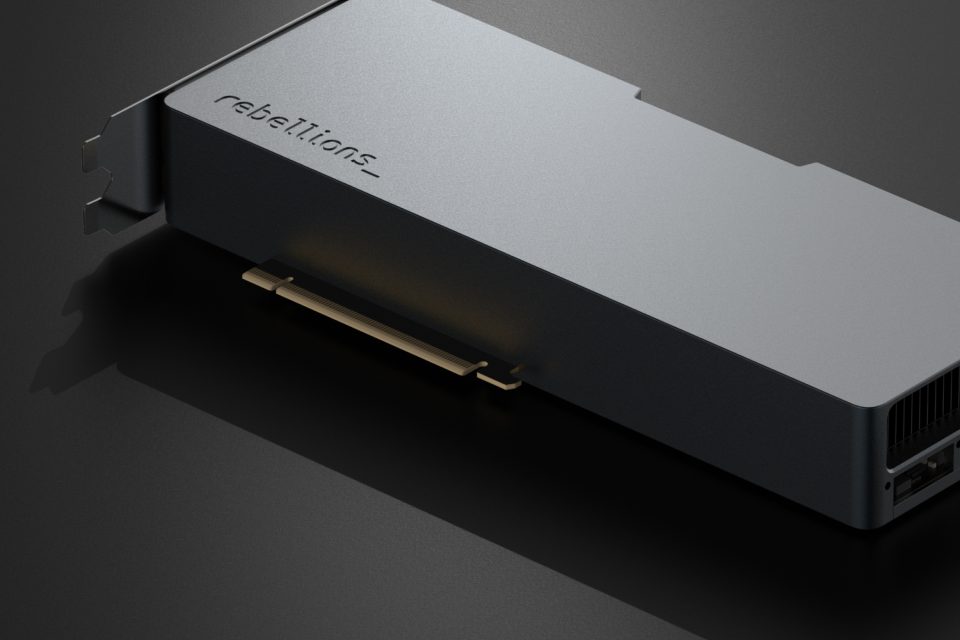
ATOM™-Max Server is a power-efficient, single-server solution built for large-scale AI inference. It supports up to 8 ATOM™-Max PCIe cards, enabling deployment of hundreds of AI models spanning vision, LLMs, multimodal, and even physical AI workloads. Fully compatible with leading inference frameworks like vLLM, Triton, and Kubernetes, you can seamlessly transition from GPU workflows with familiar tools and guided tutorials.
1,024 TFLOPS (FP16)
Peak Performance
Maximum FP16 Performance
512GB, 1TB/s
GDDR6 Memory
High-Capacity, High-Bandwidth Memory
~4.4kW
Power Consumption
Built for Optimal Energy Use
4U
Form Factor
Optimized for Data Centers
Compatible Software
OS
Ubuntu, Rhel 9, AlmaLinux, Rocky Linux
Frameworks & Tools
Hugging Face, PyTorch, TensorFlow, Triton
Inference Serving
VLLM, Triton Inference Server, TorchServe
Orchestration
Docker, OpenStack, Kubernetes, Ray
Performance at
Any Scale

Even under heavy demand, the ATOM™-Max delivers stable, high-throughput performance—generating thousands of tokens and processing image frames per second, all from a single system.
Sustainable
AI Infrastructure

ATOM™-Max delivers maximum AI inference performance within limited server room power budgets. Its exceptional power efficiency significantly lowers total cost of ownership (TCO) and enables a more sustainable AI infrastructure.
Full-stack
Software Support

ATOM™-Max is compatible with popular open-source ecosystems, supporting efficient serving, flexible resource management, and monitoring through tools like vLLM, Triton, Kubernetes, and Prometheus—so you can build full end-to-end services with ease.
Variety of
Models and Applications

Run hundreds of AI models out of the box—from LLMs and vision AI to multimodal and physical AI. Build tailored services like chatbots, search, summarization, smart CCTV, and image generation.
Develop
As You Always Have

No need to abandon your existing development environment. Start right away with familiar workflows (PyTorch, TensorFlow, etc.) and step-by-step tutorials.
Applications
Enterprise
Streamline enterprise-wide AI adoption—from development to deployment—with scalable AI infrastructure
Construction
Enable proactive safety monitoring on construction sites with AI-powered surveillance
Healthcare
Support the AI healthcare ecosystem, from personalized wellness to precision medicine
Finance
Build next-gen financial services with secure, real-time AI processing of financial data
Manufacturing
Boost manufacturing productivity with Physical AI-powered smart factories
Telecom
Power advanced telecom services and elevate customer experience with reliable large-scale AI operations.
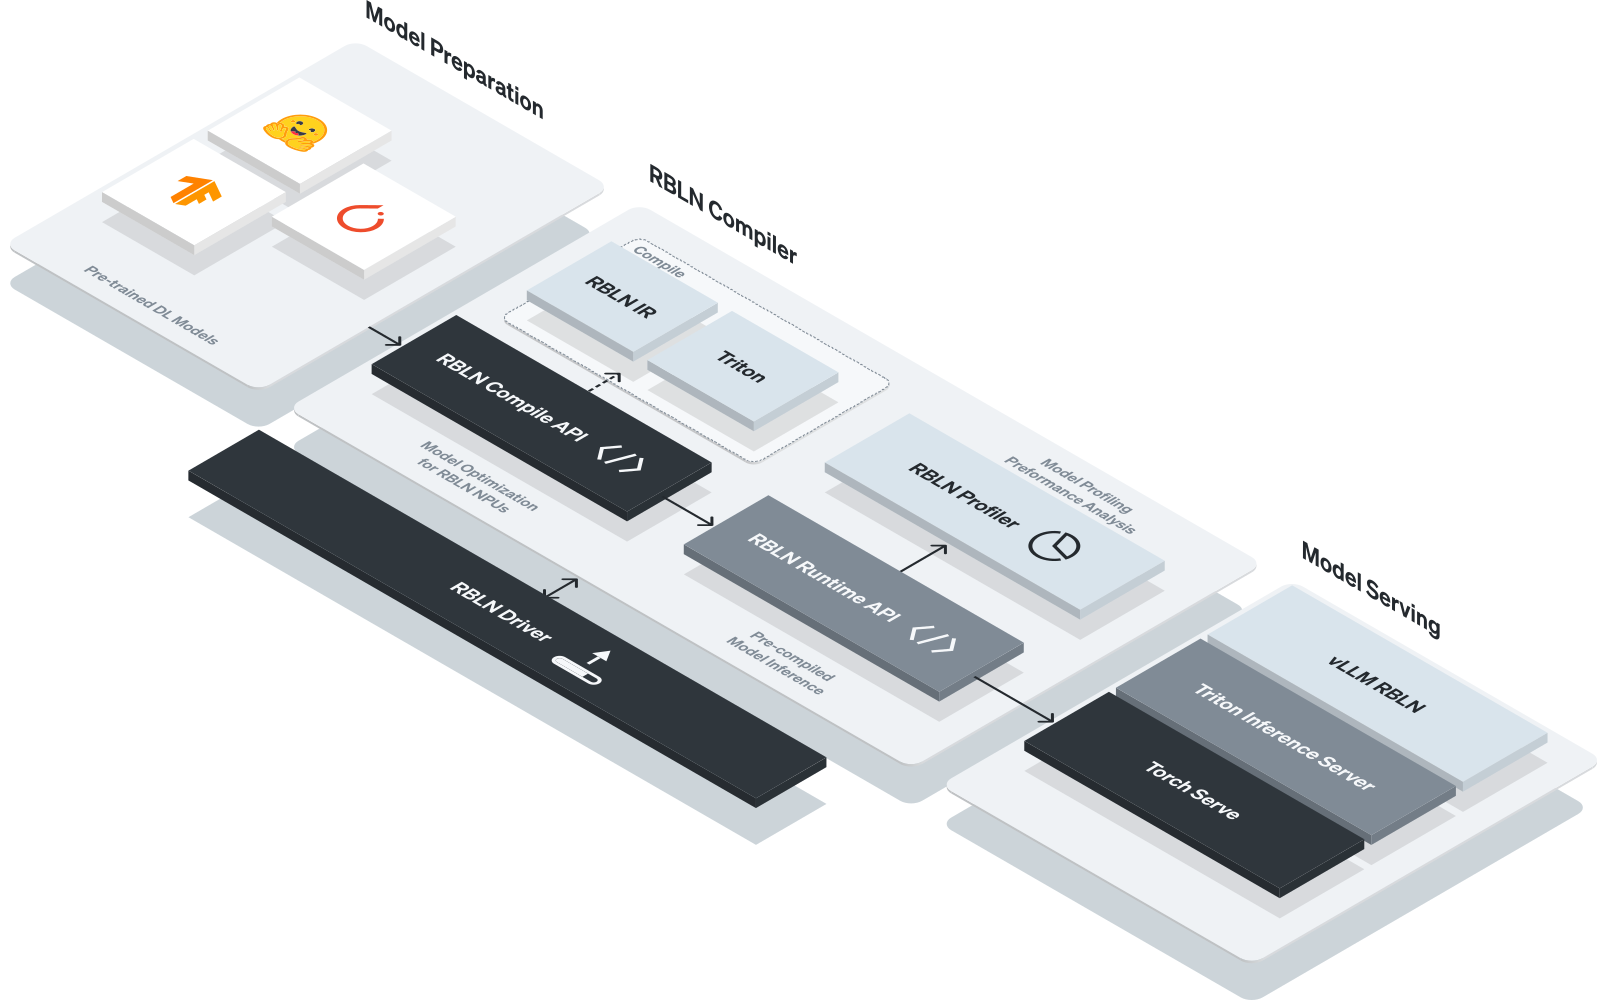
Rebellions SDK
Deploy with Confidence from Day One.
Driver SDK
Core system software and essential tools for NPU excution
NPU SDK
Developer tools for model and service development
Model Zoo
300+ ready-to-use PyTorch and TensorFlow models optimized for Rebellions NPUs