Rebellions SDK
Deploy with Confidence from Day One.
Built for developers who scale AI
Rebellions delivers the performance and efficiency of custom AI silicon—without compromising the software experience.
From PyTorch and vLLM to Triton, our stack offers a seamless, GPU-like workflow optimized for real-world AI inference at scale.
Unified Inference Stack That Just Works
A GPU-class software experience designed for scalable AI inference
- Native integration with PyTorch, vLLM, and Triton
- Broad model support including MoE and decoder-only LLMs
- Production-proven in high-concurrency, latency-sensitiev environments
PyTorch-Native Inference Engine
Purpose-built for real-world PyTorch workflows
- Graph-mode optimization for hardware-accelerated execution
- Eager mode for flexible experimentation and prototyping
- Distributed inference via Collective Communication Library
- Intelligent precision control across FP32, FP16, FP8, FP6, and FP4
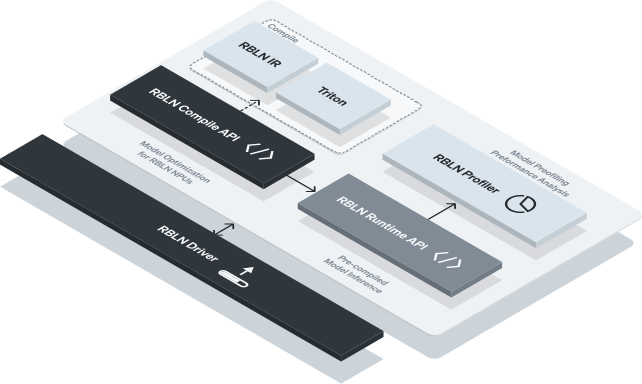
vLLM Serving, Optimized for Concurrency
High-throughput LLM serving with native PyTorch support
- Ideal for high QPS workloads with long-context models
- Standard PyTorch API compatibility
- Hugging Face integration for fast model onboarding
Triton SDK & Developer Tooling
Low-level programmability meets developer-friendly design
- Triton backend with custom kernel programming support
- Intuitive APIs for seamless integration into ML pipelines
- Built-in profiling and debugging tools
- Extensive docs and real-world example codes
Featured Resources
Related Products
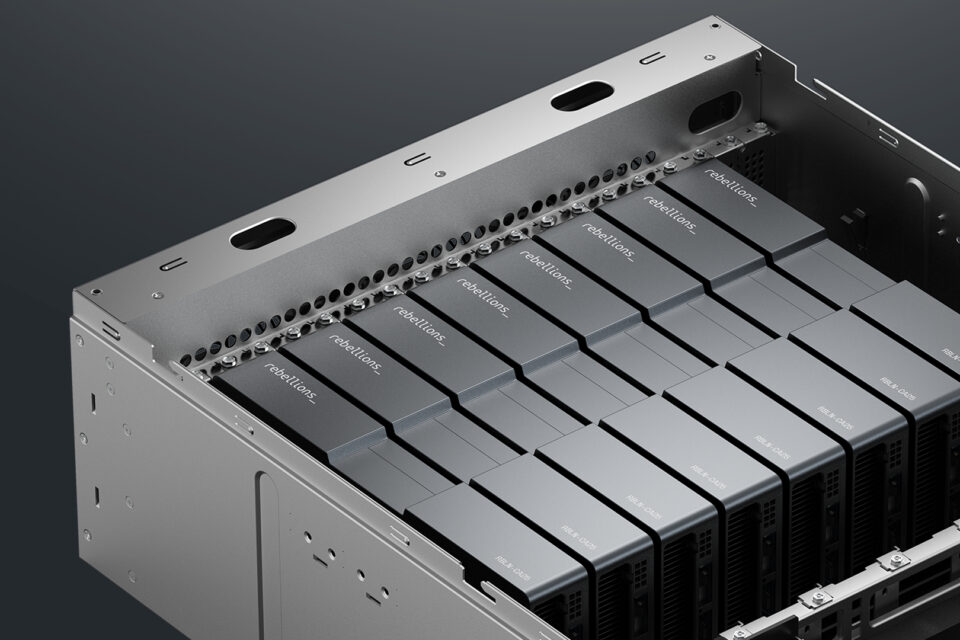
ATOM™-Max Server
Large-Scale AI Inference
Starts with a Single Server
ATOM™-Max Pod
High-Performance AI Cluster with
Rack-to-Rack Scalability and RDMA Networking
REBEL-Q
HBM3e chiplet-based scalable Al accelerator
for hyperscale workloads
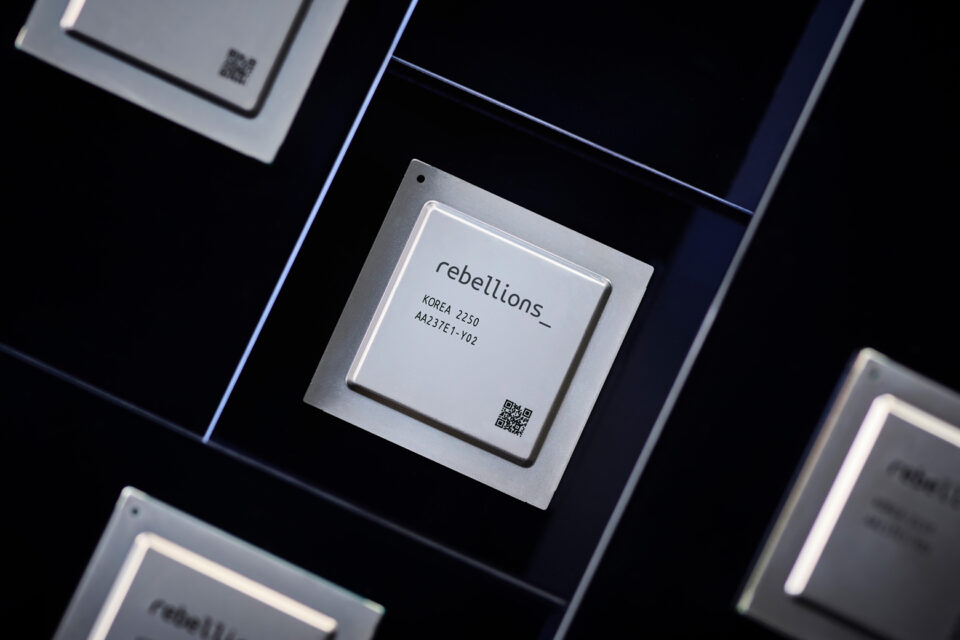
ATOM™ SoC
GDDR6 SoC for versatile Al inference at high TPS/Watt